Observability Engineering Services
Design, implement and optimise observability across AWS, Kubernetes and complex distributed systems. Bion provides hands-on engineering expertise in OpenTelemetry, telemetry pipelines, performance diagnostics and observability cost optimisation, helping teams build reliable, efficient and maintainable monitoring environments.
Observability Engineering for Modern Infrastructure
Modern applications generate telemetry across microservices, containers, cloud infrastructure and distributed workloads. Without consistent instrumentation and well-designed data pipelines, engineering teams can face fragmented visibility, rising monitoring costs and complex incident investigations.
Bion works alongside SRE, Platform Engineering and development teams to design and improve observability architectures that support production reliability and long-term operational efficiency.
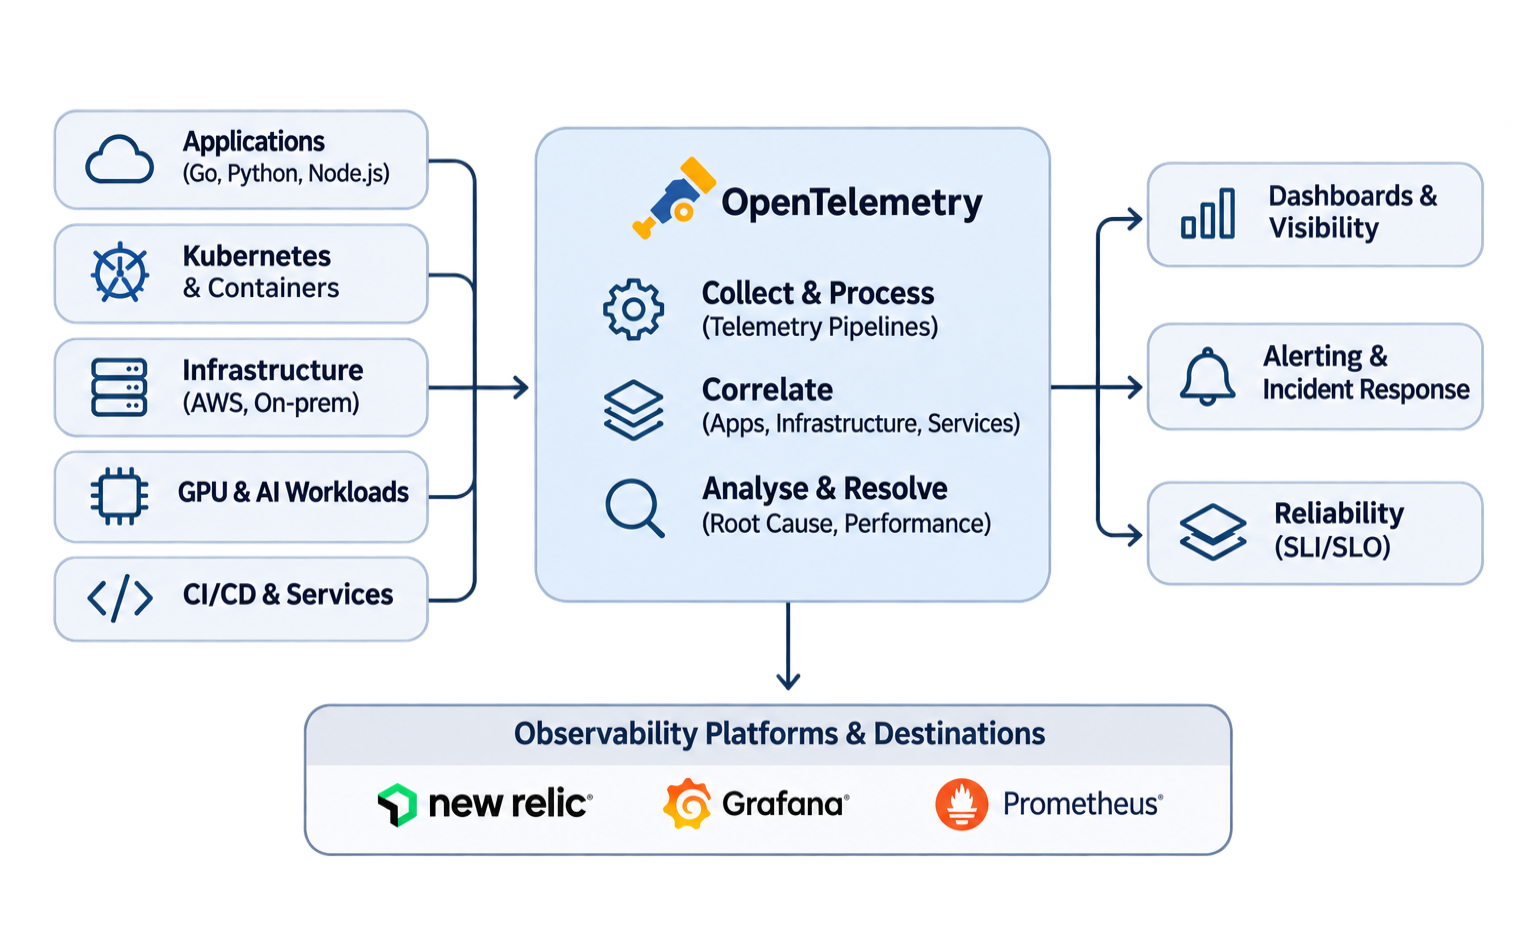
What Our Observability Engineering Services Covers
1. Observability Architecture & Platform Engineering
Build observability architectures that support your infrastructure, applications and engineering teams.
We design and implement telemetry architectures across cloud-native, hybrid and distributed environments, integrating existing monitoring platforms and open-source technologies.
-
Architecture Design: Telemetry collection, processing, storage and integration strategies.
-
Cloud & Infrastructure: Observability across AWS, Kubernetes, containers and serverless workloads.
-
Platform Integration: OpenTelemetry integration with New Relic, Grafana-based stacks and other observability backends.
-
Infrastructure Automation: Consistent deployment and configuration of observability components using Infrastructure as Code and GitOps.
2. OpenTelemetry Instrumentation & Engineering
Standardise how telemetry is generated and collected across your applications and services.
We help engineering teams adopt OpenTelemetry, replace proprietary instrumentation where appropriate and establish consistent practices for distributed tracing, metrics and structured logging.
-
Application Instrumentation: OpenTelemetry SDKs, automatic and manual instrumentation.
-
Distributed Tracing: Trace context propagation across services, APIs and dependencies.
-
Instrumentation Migration: Transition from proprietary agents and instrumentation to OpenTelemetry.
-
Shared Standards: Reusable instrumentation patterns, semantic conventions and developer guidance.
3. Telemetry Pipeline Engineering
Build and optimise the pipelines responsible for collecting, processing and delivering observability data.
We design OpenTelemetry Collector architectures that handle telemetry across multiple services, environments and backend platforms while maintaining data quality and operational efficiency.
-
Collector Architecture: Deployment, configuration and scaling of OpenTelemetry Collectors.
-
Data Processing: Filtering, enrichment, transformation and batching.
-
Telemetry Routing: Exporting metrics, logs and traces to the appropriate observability backends.
-
Pipeline Reliability: Monitoring Collector performance, resource consumption and data delivery.
4. Telemetry Cost & Performance Optimisation
Control observability costs without losing the data needed to investigate critical issues.
We analyse telemetry generation, processing and ingestion to identify unnecessary data volumes and improve pipeline efficiency across applications and infrastructure.
-
Sampling Strategies: Head-based and tail-based trace sampling.
-
Metric Cardinality: Identify and manage high-cardinality metrics and unnecessary dimensions.
-
Data Volume Optimisation: Reduce redundant logs, metrics and traces through filtering and collection policies.
-
Pipeline Efficiency: Optimise resource utilisation, processing overhead and backend ingestion.
5. Performance & Reliability Engineering
Improve how engineering teams investigate application behaviour, identify performance bottlenecks and measure service reliability.
We connect observability data with practical performance engineering and SRE practices to help teams understand complex production environments.
-
Performance Diagnostics: Distributed tracing, latency analysis and service dependency investigation.
-
Full-Stack Correlation: Connect application telemetry with Kubernetes, infrastructure and database performance.
-
Service Reliability: Define meaningful Service Level Indicators (SLIs) and Service Level Objectives (SLOs).
-
Incident Investigation: Improve troubleshooting workflows, alert quality and root-cause analysis.
6. Observability Automation & Engineering Enablement
Make observability a consistent part of software development and platform operations.
We work with engineering teams to establish reusable tooling, shared standards and automated workflows that support service ownership and ongoing observability improvements.
-
Observability as Code: Automate configuration, deployment and management of observability components.
-
Developer Enablement: Shared libraries, instrumentation templates and onboarding practices.
-
Service Ownership: Consistent telemetry, dashboards and alerting standards across teams.
-
Engineering Support: Project-based implementation, specialist engineering capacity and ongoing optimisation.
Explore How We Helped Our Customers
Bion has supported organisations across retail, financial services and hospitality with observability architecture, application monitoring and performance optimisation.
Our work demonstrates how tailored engineering solutions can improve service visibility, incident response and monitoring efficiency.
-
Cost-Effective Observability for a Global Retailer
50% reduction in monitoring costs | 35% faster incident response
We helped a global fashion retailer optimise New Relic data ingestion, improve Kubernetes monitoring and establish application performance visibility across distributed services.
-
Enhancing Observability for a Global Financial Institution
Over 50% lower latency | 73% fewer transaction failures
We helped a financial institution improve visibility across hybrid cloud infrastructure, distributed applications and critical transaction flows, supporting faster diagnosis and greater service reliability.
-
Monitoring and System Reliability for Warner Hotels
We implemented centralised monitoring across AWS and Azure environments, integrating application visibility, infrastructure metrics, logging and proactive alerting to support more reliable digital operations.


Build a More Efficient and Reliable Observability Environment
Whether you're adopting OpenTelemetry, improving an existing observability platform or optimising telemetry costs, Bion provides specialist engineering support tailored to your infrastructure and operational requirements.
We work with your engineering teams to design, implement and improve observability across applications, infrastructure and distributed systems.
Discuss your observability engineering requirements with our team.